I’ll be presenting our TMLR paper at NeurIPS in Sydney this December as part of the Reproducibility Track. The paper brings Heek et al.’s multistep consistency distillation algorithm to continuous-time consistency models in the TrigFlow formulation.
Our work on bringing Heek et al.’s multistep consistency distillation algorithm to the TrigFlow formulation is now published in TMLR! We also share our experience reproducing sCM and have released the code and model weights.
AlphaFold 3 and Boltz-2 spend about 200 denoising steps turning noisy coordinates into a molecular structure. With Blitz, we bring that down to eight by training the model to make a series of shorter updates. We also adjust the noise schedule and allow for optional physical steering for Boltz-2. Across our evaluations, Blitz broadly matches the teachers’ structural accuracy, and AF3-Blitz improves on its teacher on several accuracy measures.
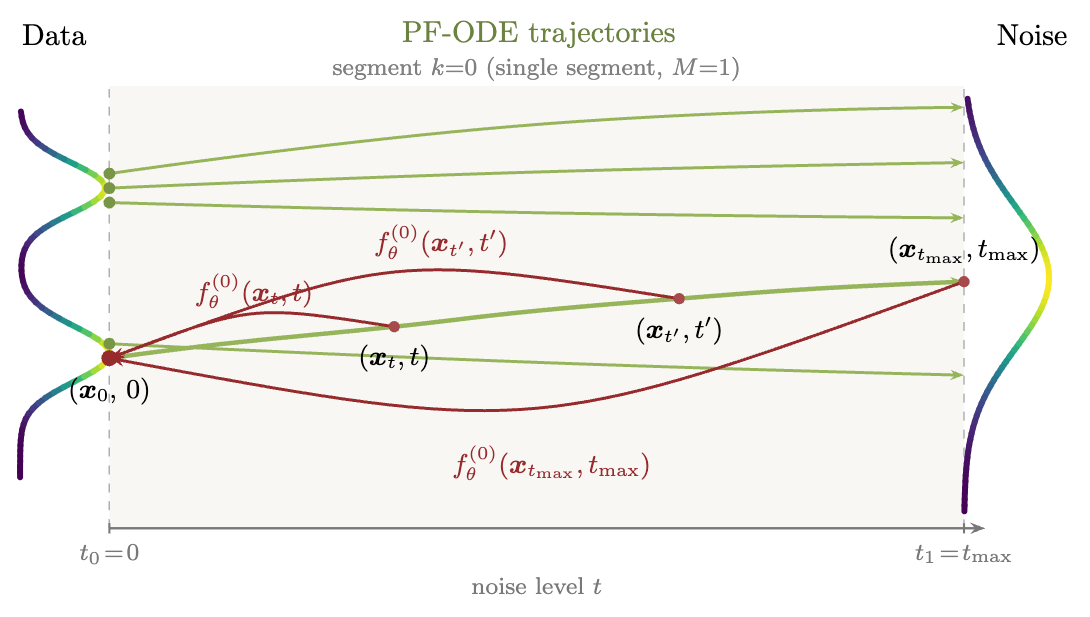
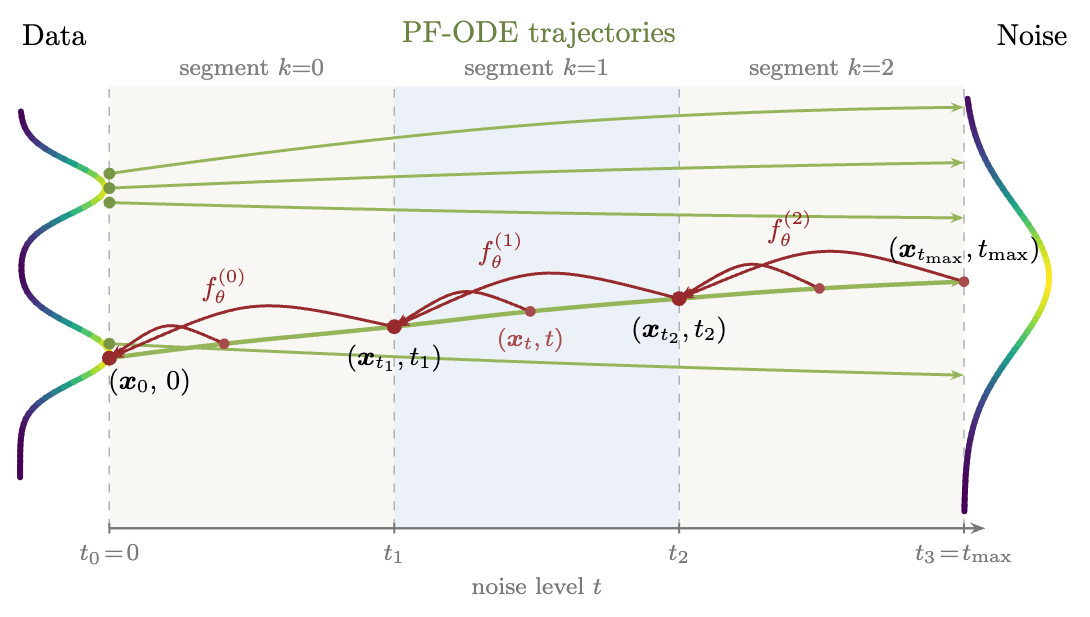
We brought Heek et al.’s multistep consistency distillation algorithm to continuous-time consistency models in the TrigFlow formulation. We call this adaptation MS-sCD and use it to generate images through a small number of learned updates. Instead of learning a single mapping from noise to a clean image, the model learns shorter mappings across segments of the diffusion trajectory. The figure below illustrates this with one segment on the left and three on the right. We evaluated two-, four-, and eight-step generation on CIFAR-10 and ImageNet-64. Alongside this, we conducted an independent reproduction study of sCM, trained the teacher models from scratch, and documented the implementation details. We have made the code and all teacher and student model weights openly available.
The goal of this project was to provide an open source implementation of the Moment Matching framework by Salimans et al. to distill image diffusion models. Unlike consistency distillation, this is fundamentally a distribution matching problem, allowing the student to match a higher performing stochastic teacher. The core objective is to ensure the conditional expectation of clean data given a noisy observation remains identical between the true data and the distilled model. We use an alternating optimization setup where an auxiliary denoising model estimates this exact expectation, denoted as , where is the generator distribution, is the generated data, and is the noisy observation at step . By matching these moments, our 8 step distilled model reaches an FID of 1.4. Training code, checkpoints, and the full implementation are on GitHub.
This project addresses the deployment and computational hurdles of modern biomolecular prediction and design models like AlphaFold 3, Boltz 2, Chai 1, and RFdiffusion. To make these tools more accessible, we developed optimized open source Singularity containers for both x86 and ARM architectures. Because multiple sequence alignment generation is highly resource intensive, we also built OmniFold. This platform runs these models simultaneously, recycles alignments across algorithms to save compute, and automatically generates a unified quality control report. All containers and code are publicly available to help researchers bypass infrastructure bottlenecks. A preprint is available here, and the OmniFold code is on GitHub.
Developed an optimized open-source implementation of AlphaFold 2 & 3 in joint work with Prof. William Lai at the Epigenomics Facility at Cornell University that addresses a fundamental challenge in computational structural biology: resource inefficiency. The AlphaFold workflow has roughly 75% of runtime consumed by CPU-intensive multiple sequence alignment (MSA) generation, with GPU resources only required for the final structure prediction phase. Our solution separates these phases within a single Open OnDemand (OOD) instance. This work was presented at the Global Open OnDemand Conference at Harvard University in March 2025. Our work has been adopted by several major HPCs in the United States and around the world. The code is available here.
This project is part of my M.Sc thesis under the supervision of Prof. Soundar Kumara and Prof. Peter Butler at Penn State. It aims to extract insights from biomedical literature by generating word embeddings to create weighted word networks. Due to the advances in large language models, biomedical named entity recognition has become much more reliable. Hence, depending on the research question, we use keywords to extract relevant information from these embedding models while carefully selecting the data sources for training. When limiting our models to literature published before a specific year, we discovered mentions of entities in our network that were not officially recognized until later, providing new avenues for the research questions we are investigating.

